Predictive Multiplicity in Cell-Fate Assignment: Label-Free Rashomon Sets and the Limits of Per-Cell Certification
In depth10:40CCAI
paperi.ai
0:00 / 0:00
Arjun Bhupatiraju, Abhiram Bhupatiraju
What if several cell-fate models fit the data equally well, yet disagree about individual cells? This paper finds that model multiplicity is real, and that certifying a fate across all those models can make predictions worse.
Single-cell trajectory inference maps transcriptomic measurements onto developmental continua, yet parameter con-figurations that fit the data with equivalent statistical fidelity can assign conflicting cell fates. This paper presents FateMultiplicity, a label-free framework that constructs a statistically admissible model set, or Rashomon set, without ground-truth lineage labels, by evaluating model discrepancy on cross-fitted held-out genes under non-inferiority testing calibrated against random-seed variation. Multiplicity so measured is large, and depends more on the diversity of the model space than on its size: twelve configurations of a second algorithm expose 20.0% of cells where twenty-four of the first expose 3.8%. Whether the resulting per-cell certified fate margin FM yields more reliable assignments than the fitted model already provides is then tested, and it does not. On simulation ground truth, with every statistic computed on the same cells, FM discriminates misassignment at AUC 0.682 against 0.965 for the baseline configuration’s own decision margin (p = 0.003) and 0.854 for a seed-dispersion baseline needing no acceptance region. The failure is mechanistic and specific to the lower tail. Informativeness is governed by the breadth of the admitted set rather than its cardinality: at fixed cardinality four, seed refits give 0.933 and hyperparameter-perturbed sets 0.701. Relaxing the infimum to a q-quantile recovers discrimination monotonically but converges toward the single model’s own confidence rather than exceeding it, and the supremum over the same margins reaches 0.973 because θ∗’s own membership bounds it from below. The infimum alone is unanchored, free to report whichever admitted configuration disagrees most. Multiplicity in trajectory inference is therefore worth measuring and reporting, while per-cell certification over a label-free Rashomon set is not a route to more reliable fate calls. Two constructions survive: a margin-erosion ratio separates real from spurious branch points in simulation (AUC 0.890, untested on real data) where certification cannot, and against clonally observed fate, uncertified cells disagree with their clone’s outcome 16.4 percentage points more often than certified cells (p < 0.001).
Transcript
What if several cell-fate models fit the data equally well, yet disagree about individual cells? This paper finds that model multiplicity is real—and that certifying a fate across all those models can make predictions worse. Single-cell RNA sequencing enables reconstruction of continuous cellular differentiation trajectories from snapshot transcriptomic data.
Trajectory inference methods order individual cells along pseudotemporal axes and compute fate probabilities to identify lineage commitment points. But these pipelines rely on dimensionality reduction, nearest-neighbor graph construction, pseudotime ordering, and absorbing random walks, each governed by parameters the analyst selects.
Predictive multiplicity has been studied extensively in supervised classification, where an explicit loss defines the admissible set. Single-cell trajectory inference has no such loss because true fate labels are rarely available, so the Rashomon set cannot be defined in the usual way.
FateMultiplicity evaluates candidate configurations against held-out genes with a cross-fitted discrepancy metric. It admits models through non-inferiority testing calibrated against random-seed noise. The certified fate margin, or FM, is the minimum decision margin over all statistically admissible configurations.
Four datasets are used, including mouse spinal cord injury data from GEO GSE162610. That first dataset contains 66,178 cells over four timepoints and two dissociation protocols, with annotations identifying 19,818 microglia. After removing 118 high-ribosomal cells, the analysis was restricted to 10x v2 chemistry and used a sample-stratified subsample of 6,000 cells and 15,787 genes.
Highly variable genes construct the trajectory, while held-out genes assess model discrepancy. This separates the genes used to build the trajectory from the held-out genes used to assess model discrepancy. The baseline uses an absorbing random walk solved as a sparse linear system, with 2,000 highly variable genes, 30 principal components, and 15 nearest neighbors.
The baseline also uses seed 20260808, a backward step penalty of 0.05, and no teleportation. The walk’s internal geodesic pseudotime is both the ordering scored by the discrepancy metric and the ordering driving the transition operator.
Model performance is evaluated without ground-truth labels by assessing the expression smoothness of held-out genes along the inferred pseudotime ordering. A candidate configuration is fitted strictly on training genes and evaluated on held-out genes across folds.
Unsupervised trajectory inference lacks a labeled loss and a scale for the tolerance parameter used in a usual Rashomon set. FateMultiplicity replaces the loss with cross-fitted held-out discrepancy, measuring fit against gene sets excluded during estimation rather than absent labels.
The fixed threshold becomes a hypothesis test, with its width derived from the empirical dispersion of held-out scores at a stated significance level. Held-out genes are grouped into modules through average-linkage hierarchical clustering on one minus the absolute Spearman correlation.
The genes are clustered into 15 to 17 modules per fold, or 48 total blocks, to prevent correlated expression from artificially inflating effective sample size and spuriously narrowing the acceptance region. Validation against known ground truth uses synthetic single-cell trajectories.
Expected expression combines a latent progression variable, a branch assignment, a batch effect, and gene-program membership across seven programs. Counts are drawn from a negative binomial with dispersion 0.20, followed by count thinning.
A cell is certified if its certified fate margin is greater than zero, meaning every admitted model agrees on the categorical call. A cell is uncertified if its certified fate margin is less than or equal to zero. The companion supremum measures upper-bound certainty, but in the empirical objects it is above one minus a thousandth for more than 97% of cells and does not separate biological ambiguity from algorithmic instability.
Across statistically indistinguishable parameter settings, reported fate confidence for individual cells varies by up to 483-fold. Within any one configuration, the distribution of per-cell margins is narrow, so reported confidence is closer to a property of the configuration than of the cell.
One admitted configuration with a 50-neighbor graph calls 2.5% of cells confident, while another with 6,000 variable genes calls 100% confident. In panel A, the rows form a staircase of tightly concentrated bands, with their median ticks shifting from near zero to nearly one across configurations.
Panel B shows the same contrast: points spread widely along the decision-margin axis while remaining compressed near the top of the agreement axis, indicating little corresponding movement in categorical assignments. Evaluating 24 single-factor perturbations within the absorbing-walk grid yields a baseline multiplicity rate of 3.8%.
A seed replicate also passed and was admitted as a 25th member, adjusting the rate to 3.9%, or 235 of 6,000 cells. Adding twelve Palantir configurations grows the admissible set to 36 and raises the rate to 20.4%. In panels A and B, the overturned cells appear in compact patches, especially near the edges of the major manifold regions, rather than being evenly scattered.
In panel C, the two protocol bars show the largest separation at one day post-injury, while the bars are much closer by seven days. At matched cardinality, the increase in multiplicity is driven by structural diversity rather than model count. Sampling 24 configurations restricted to the absorbing walk leaves the rate at 3.8%, while sampling 24 spanning both algorithms raises it to 17.3%.
Most strikingly, twelve Palantir configurations expose 20.0% of cells, whereas twenty-four absorbing-walk runs expose 3.8%. In panel A, the blue pooled curve stays visibly above the orange absorbing-walk curve across the range, while the purple Palantir curve rises sharply at smaller ensemble sizes.
In panel B, the bars generally climb from left to right, reaching their tallest height at the largest matched configuration set. Only the barcoded object supplies fate labels, so FM’s ability to predict misassignment is measurable on two of the four arms. On those two arms, the higher certification-power value has the higher area under the curve: 0.615 at Pi equal to 1.14, against 0.568 at Pi equal to 1.02.
A model space whose disagreement does not exceed its own seed floor has certified nothing, and that belongs beside any fate claim drawn from a certified margin. In panel A, the microglial marker sits farthest to the right, while the other arms cluster near the dashed unity line or slightly to its left.
In panel B, the microglial point is visibly separated above the diagonal, whereas the remaining points lie close to that reference, showing much less model-space disagreement relative to their seed floors. FateMultiplicity quantifies predictive multiplicity in unsupervised trajectory inference without ground-truth labels by replacing supervised loss tolerances with seed-calibrated non-inferiority testing on held-out genes.
Model diversity drives observed ambiguity far more than configuration count: twelve runs of one algorithm expose more multiplicity than twenty-four of another. Multiplicity is not uniform across a tissue; in injured spinal cord it peaks during the acute phase, when transcriptional state changes fastest.
A multiplicity rate is uninterpretable without certification power, which spans 2.16 to 0.83 across four arms, so rates from different arms are not comparable quantities. Figure five validates the simulation on the corrected cohort in three views.
Panel A shows misassignment falling from thirty-one percent in the lowest FM quintile to zero percent in the highest, while panel B shows per-object behavior on both sides of FM equals zero across forty-three objects, with the mean in black. Panel C shows certification near zero point nine seven for the two scenarios without a true fork, compared with zero point five five to zero point five nine for the three scenarios containing one, highlighting why certification alone cannot distinguish a real fork from an arbitrary partition.
Figure six shows that per-cell certification depends more on how models disagree than on how many models are aggregated. In panel A, replacing the infimum with higher quantiles raises discrimination toward the baseline model’s own confidence, while panel B shows that, at cardinality four, seed refits and hyperparameter-perturbed configurations have AUC values of zero point nine three three and zero point seven zero one.
Panel C reports a monotonic decline as randomly drawn subsets grow from two to eight configurations, supporting the authors’ conclusion that the aggregator—not the underlying quantity—limits certification. FateMultiplicity shows that ambiguity is worth measuring and reporting, especially when different algorithms disagree.
But its per-cell certified fate margin does not improve reliability over simpler model-specific or seed-based margins.
A derivative work by Paperi · AI-generated script, voice and captions
· pages and figures unaltered
Made with Paperi.
Drop in a research PDF — get a narrated video walkthrough like this one,
with highlights that follow the narration. Free to start.
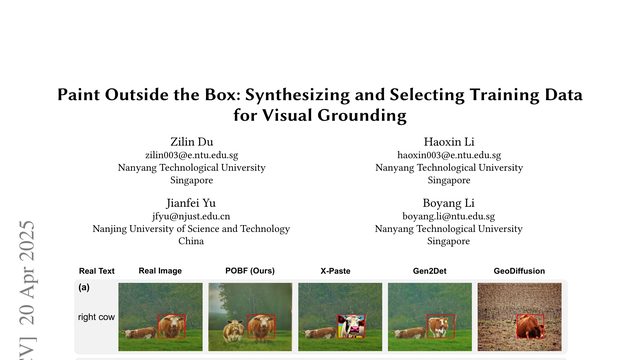
Teaching a computer to find the exact object described in a sentence usually demands vast amounts of carefully labeled pictures. This paper shows how carefully made artificial examples can help when those pictures are scarce.What if the safest way to generate a labeled object image is not to redraw the object at all? This paper paints outside the box, then filters the synthetic examples before training.
Raúl Pérez‐López, Rubén González-Vallejo, Laura Lucia‐Palacios, Iguácel Melero‐Polo, Andreea Trifu
When ChatGPT gives writing advice, students may trust it not only because of what it says, but because the system seems capable and understanding. That trust is linked to how much learning they feel has happened.ChatGPT’s feedback may feel more credible when the system seems competent and empathetic, but that credibility does not matter equally to every student. This study traces how social impressions become learning perceptions.
Medical records can help prevent disease and improve treatment, even when parts of a patient’s story are missing. But the way those blank spaces are handled can quietly change the conclusion doctors and researchers reach.Electronic health records can improve prevention, treatment, research, and even pandemic response, but the review finds that missing data are often handled inconsistently, leaving important uncertainty behind.
 4:48