Predictive Multiplicity in Cell-Fate Assignment: Label-Free Rashomon Sets and the Limits of Per-Cell Certification
Overview4:24CCAI
paperi.ai
0:00 / 0:00
Arjun Bhupatiraju, Abhiram Bhupatiraju
A cell can receive radically different fate confidence from models that fit the same data equally well. The unsettling part is that adding more plausible models does not necessarily make any one cell’s fate call more trustworthy.
Single-cell trajectory inference maps transcriptomic measurements onto developmental continua, yet parameter configurations that fit the data with equivalent statistical fidelity can assign conflicting cell fates. This paper presents FateMultiplicity, a label-free framework that constructs a statistically admissible model set, or Rashomon set, without ground-truth lineage labels, by evaluating model discrepancy on cross-fitted held-out genes under non-inferiority testing calibrated against random-seed variation. Multiplicity so measured is large, and depends more on the diversity of the model space than on its size: twelve configurations of a second algorithm expose 20.0% of cells where twenty-four of the first expose 3.8%. Whether the resulting percell certified fate margin FM yields more reliable assignments than the fitted model already provides is then tested, and it does not. On simulation ground truth, with every statistic computed on the same cells, FM discriminates misassignment at AUC 0.682 against 0.965 for the baseline configuration’s own decision margin (p = 0.003) and 0.854 for a seed-dispersion baseline needing no acceptance region. The failure is mechanistic and specific to the lower tail. Informativeness is governed by the breadth of the admitted set rather than its cardinality: at fixed cardinality four, seed refits give 0.933 and hyperparameter-perturbed sets 0.701. Relaxing the infimum to a q-quantile recovers discrimination monotonically but converges toward the single model’s own confidence rather than exceeding it, and the supremum over the same margins reaches 0.973 because θ∗’s own membership bounds it from below. The infimum alone is unanchored, free to report whichever admitted configuration disagrees most. Multiplicity in trajectory inference is therefore worth measuring and reporting, while per-cell certification over a label-free Rashomon set is not a route to more reliable fate calls. Two constructions survive: a margin-erosion ratio separates real from spurious branch points in simulation (AUC 0.890, untested on real data) where certification cannot, and against clonally observed fate, uncertified cells disagree with their clone’s outcome 16.4 percentage points more often than certified cells (p < 0.001).
Transcript
A cell can receive radically different fate confidence from models that fit the same data equally well. The unsettling part is that adding more plausible models does not necessarily make any one cell’s fate call more trustworthy. Single-cell measurements can reconstruct continuous paths of cellular change from snapshots, and these methods order individual cells along those paths and calculate likely fates to find points where cells commit to a lineage.
But these pipelines rely on complex chains of steps, each governed by parameters the analyst selects. That means reasonable choices can shape the answer before the biology gets a vote. So the framework evaluates candidate configurations on genes held back from fitting and admits models whose differences are no larger than the variation caused by random seeds.
The resulting certified fate margin is the minimum decision margin over all statistically admissible configurations. In plain terms, it asks how weak the fate call becomes across the models still considered acceptable. The claim is deliberately narrow: a model set can be constructed without ground-truth labels, not that the measure of multiplicity is new.
The key distinction is how the set is drawn when no observed outcome exists to define a usual error measure. Once an admissible set is constructed, downstream analysis follows standard practice. Across parameter settings that are statistically indistinguishable, reported fate confidence for individual cells varies up to 483-fold.
Within any one configuration, nearly every cell receives nearly the same value. That means reported confidence is closer to a property of the configuration than of the cell. One admitted configuration calls 2.5 percent of cells confident, while another calls 100 percent confident, and both are defensible.
But here is the surprise: multiplicity is driven more by structural diversity than by model count. Twenty-four configurations restricted to one kind of procedure expose 3.8 percent of cells, while twenty-four spanning both kinds raise that to 17.3 percent.
Most strikingly, twelve configurations of one algorithm expose 20.0 percent of cells, where twenty-four runs of another expose 3.8 percent. Different reasonable ways of modeling the same data reveal different fragile calls.
The visual gap widens steadily as equally sized sets become more diverse, while the single-method traces remain far apart rather than converging. The certified fate margin was introduced to give the analyst a per-cell reliability statistic that a single fitted model cannot.
But evaluated against simulated ground truth, it does not deliver one. So the central promise fails at the point that matters most: the extra caution does not deliver a reliable per-cell statistic when evaluated against simulation ground truth. Here is why agreement can mislead.
Every admitted configuration forces continuous inputs into discrete terminal states, so each one can divide unbranched data in a similar, arbitrary way. High agreement across the admitted set can therefore reflect a shared bias of the algorithms rather than biological ground truth.
It confirms that an assignment is determined within a model class, not that a real lineage split exists. The framework can still quantify predictive multiplicity without ground-truth labels, and measuring it is worthwhile because the magnitudes are large.
Model diversity drives ambiguity far more than configuration count. The practical lesson is to report how much plausible modeling disagreement exists: FateMultiplicity quantifies predictive multiplicity in unsupervised trajectory inference without ground-truth labels.
That ambiguity is driven far more by model diversity than by configuration count, so the number of runs alone can understate what the analysis reveals. The study finds that model disagreement is worth measuring, because it exposes fragile cell-fate calls.
But taking the weakest answer across plausible models does not improve reliability for an individual cell.
A derivative work by Paperi · AI-generated script, voice and captions
· pages and figures unaltered
Made with Paperi.
Drop in a research PDF — get a narrated video walkthrough like this one,
with highlights that follow the narration. Free to start.
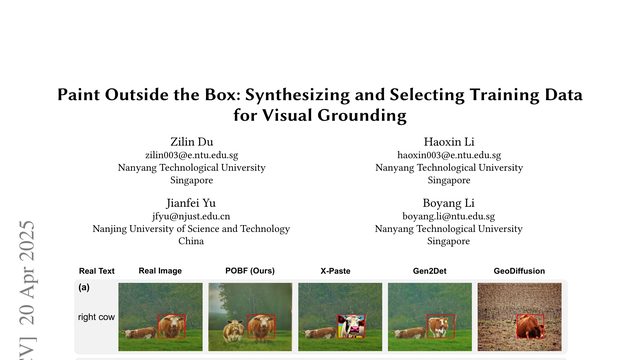
Teaching a computer to find the exact object described in a sentence usually demands vast amounts of carefully labeled pictures. This paper shows how carefully made artificial examples can help when those pictures are scarce.What if the safest way to generate a labeled object image is not to redraw the object at all? This paper paints outside the box, then filters the synthetic examples before training.
Raúl Pérez‐López, Rubén González-Vallejo, Laura Lucia‐Palacios, Iguácel Melero‐Polo, Andreea Trifu
When ChatGPT gives writing advice, students may trust it not only because of what it says, but because the system seems capable and understanding. That trust is linked to how much learning they feel has happened.ChatGPT’s feedback may feel more credible when the system seems competent and empathetic, but that credibility does not matter equally to every student. This study traces how social impressions become learning perceptions.
Medical records can help prevent disease and improve treatment, even when parts of a patient’s story are missing. But the way those blank spaces are handled can quietly change the conclusion doctors and researchers reach.Electronic health records can improve prevention, treatment, research, and even pandemic response, but the review finds that missing data are often handled inconsistently, leaving important uncertainty behind.
 4:48