Application of SMILES-based molecular generative model in new drug design
In depth6:31CCAI
paperi.ai
0:00 / 0:00
Weiya Kong, Yuejuan Hu, Jiao Zhang, Qiaoyin Tan
What if designing a drug molecule could look less like searching a massive catalog and more like generating a new sentence? This paper explores how AI models use SMILES strings to create and optimize candidate molecules.
What if designing a drug molecule could look less like searching a massive catalog and more like generating a new sentence? This paper explores how AI models use SMILES strings to create and optimize candidate molecules. Drug discovery identifies potential new therapeutic entities, while drug design finds new medications based on biological targets and the design of molecules.
The challenge is that drug discovery and design require large human, material, and financial resources. Deep generative models have attracted wide attention in drug discovery and show promise for molecular design optimization, following successes in artificial intelligence for image processing, pattern recognition, and natural language processing.
A generative model learns the distribution of molecules in a training set, then generates molecules similar to, but different from, those in that set. Among several molecular representations and generative-model categories, molecular generative models based on the text sequence SMILES are described as the most widely used.
A recurrent neural network, or RNN, accepts sequence data as input features and is used to generate new compound structures. With molecules expressed as SMILES sequences, SMILES is suitable for processing by a neural network like an RNN because it is a string sequence.
The RNN-based method can learn the low-dimensional distribution of molecular sequence grammar and chemical space from SMILES representations, and RNN has unique advantages for sequences with large differences in length distribution. RNN networks using long short-term memory and gated recurrent units have been used to generate molecular structures.
Using large numbers of SMILES molecular structures as training sets, the trained RNN models can automatically generate structures with high drug-like properties, with efficacy as high as over ninety percent and diversity basically matching the training set. A variational autoencoder consists of an encoder and a decoder.
The encoder uses a convolutional neural network to map an input molecular structure into latent variables, while the decoder uses an RNN to recover the hidden variables as the original molecule’s SMILES sequence. Because the VAE algorithm is random, different hidden variables can be sampled after training and decoded into different molecular structures.
A VAE can encode high-dimensional data in low-dimensional space and form a feature space, also called a drug space, that represents the complete set of targeted drugs to some extent. However, if all medicine-ready molecules construct the drug space, resampling produces only a new medicine-ready molecule without targeting selectivity; constructing it around a certain pocket requires many known drugs targeting that site.
The figure organizes the comparison into four labeled panels: the taxonomy appears in panel A, the left-to-right sequence flow of an RNN in panel B, the encoder–hidden–decoder pathway in panel C, and the generator–discriminator feedback loop in panel D. Visually, panel D is the only diagram showing generated data and real data converging on a discriminator.
A generative adversarial network, or GAN, was proposed by Goodfellow in twenty fourteen and was inspired by the zero-sum game. A GAN consists of two neural networks: a generator that fits the data distribution and a discriminator that judges whether the input is true.
During training, the generator outputs a hidden vector sampled from a prior distribution, while the discriminator distinguishes real data from generated-network output, forming a game between the two networks. For molecular generation, the generator creates random SMILES and the discriminator tries to distinguish those random SMILES from real molecules in the training set.
As training continues, the generated SMILES sequence becomes closer to the real molecule until the discriminator cannot distinguish whether a sequence came from the generator or the training set, allowing the generator network to generate molecules. Compared with a rule-based virtual compound library, a generative model can learn the joint probability distribution of molecular characterization and properties, enabling more effective sampling of new molecules with specific properties.
Compared with the international chemical identifier, SMILES has more rigorous syntax and uses a mapping algorithm from molecular graph to text, making it easier to process and more suitable for training machine-learning models. The choice of SMILES as molecular input avoids the same limitations as fingerprints, whose output is not directly converted into the true molecular structure and which have difficulties in de novo design.
Compared with two-dimensional molecular-graph models and three-dimensional models, SMILES-based models are computationally lower cost, more scalable to larger molecules and datasets, and able to benefit from natural-language-processing algorithm improvements. Some generative models have been successfully applied to generate new lead compounds with expected physical and chemical properties.
Even so, the application of generative models can be further explored in drug design. Despite the proliferation of SMILES-based models, they still have limitations, including a lack of explicit specification of molecular similarity, possible inability to apply existing natural-language-processing models directly, and the need to remove invalid SMILES.
Through continuous refinement, SMILES-based models are believed to become an important pillar of new drug design and help pharmaceutical chemists expedite drug discovery and design. SMILES-based generative models offer a scalable route to molecular design by treating molecules as text sequences, but invalid strings, limited similarity control, and other gaps still require refinement before the approach can fully accelerate drug discovery.
A derivative work by Paperi · AI-generated script, voice and captions
· pages and figures unaltered
Made with Paperi.
Drop in a research PDF — get a narrated video walkthrough like this one,
with highlights that follow the narration. Free to start.
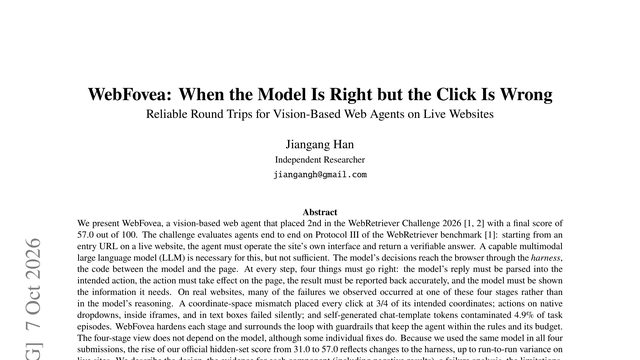
An AI can understand exactly what button to press and still fail, because the click lands somewhere else. This paper finds that the invisible machinery between the AI and the website can be as important as the AI’s reasoning.A web agent can reason correctly and still fail because its click lands in the wrong place. WebFovea argues that reliable browsing is less about smarter thoughts alone and more about making the model-to-browser round trip dependable.
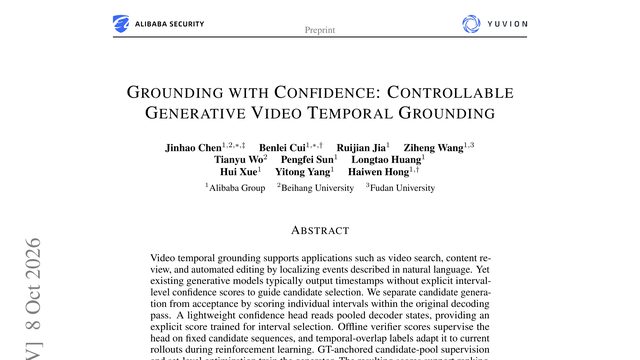
A video search system can find a clip that sounds right, but still has no idea whether it should trust that answer. This paper gives each proposed clip a separate confidence score, including permission to return nothing.What if a video model could generate several possible moments once, then decide afterward which ones deserve to be returned? This paper adds confidence without regenerating the timestamps.
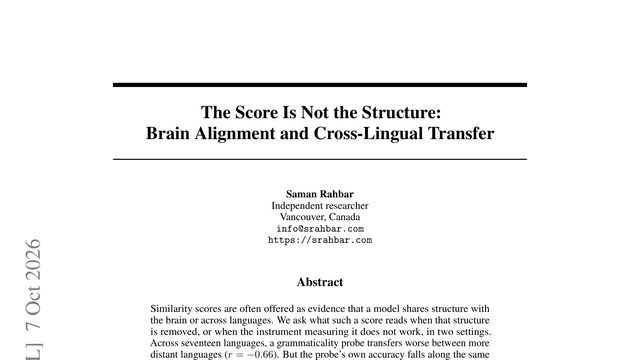
A model can score as if it matches the brain even after the brain information has been destroyed. And a language pattern can look real when the test measuring it is failing.A model can score highly against the brain, or transfer beautifully across languages, while the score mostly reflects something other than the structure researchers hoped to measure. This paper tests exactly how much correspondence survives when that structure is removed.
 3:40